How to Build a Bot Score: 11 Signals That Separate Scrapers from Shoppers
More than ten detectors score every request before anything is decided. Here is the scoreboard, what each signal is bad at, and the customers we annoyed on the way.
Part 4 of 5 in the anti-bot series. New here? Start with Part 1, the overview: Magento Anti-Bot and Anti-Scraping Guide.
Picture a nightclub bouncer with a clipboard. Not the one who refuses you for wearing trainers. The good one, who notices that you arrived in a taxi that does not exist, claim to be on the list under a name that belongs to someone else, and have been walking in and out of the door forty times without ever buying a drink.
None of those alone gets you thrown out. All of them together, and you are going home.
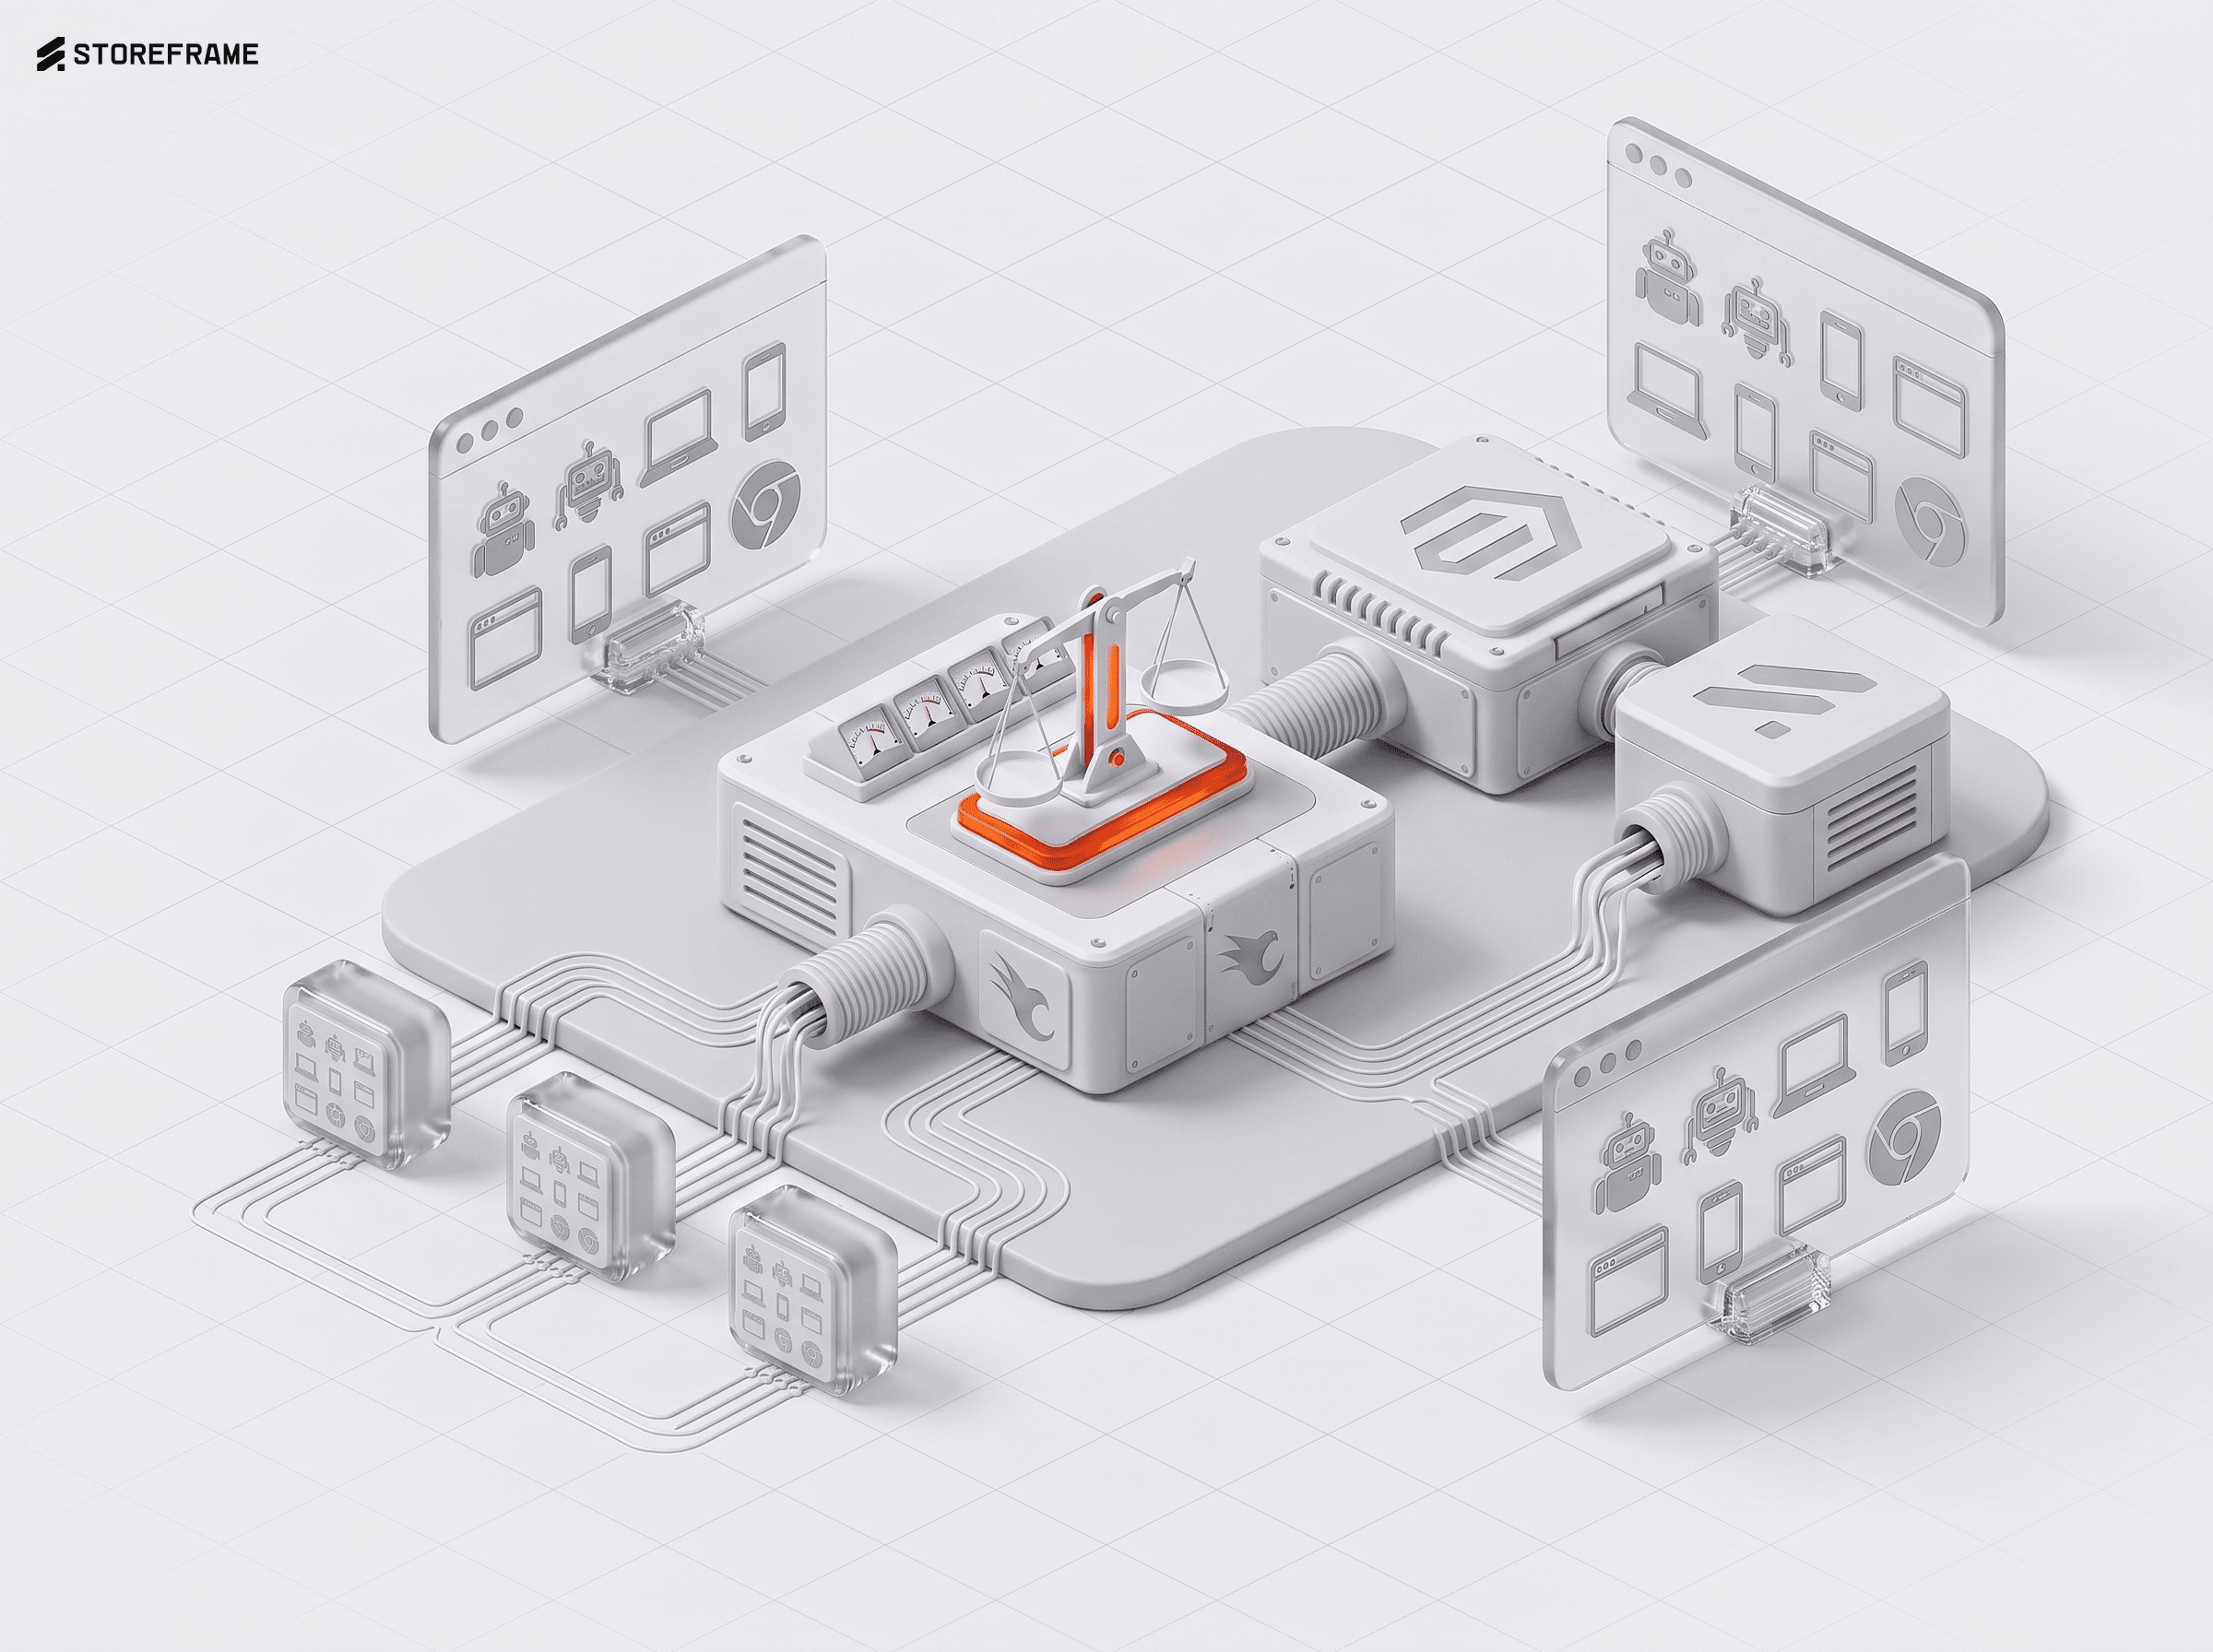
That is the job of the scoring layer at the edge of every Magento store we run. Every request gets looked at by more than ten independent detectors, each one adds to a score, and only then does anything get decided. This post opens up the scoreboard: what the signals are, what each one is good and bad at, and the embarrassing list of real customers we accidentally annoyed along the way.
First match wins was the mistake
The first version, was a list of rules. Fourteen steps, checked in order, and the first one that matched decided what happened. Simple, fast, and completely useless when something went wrong.
If a request was blocked by rule three, we never learned what rules four to fourteen thought. When a real customer got refused, the log said one reason. Usually the wrong one.
Later on we rebuilt it into four phases: a few quick exits, then every detector runs and none of them stops early, then the scores are added up into a verdict, then we log and act. Every signal is recorded on every request, whether it mattered or not. That single change is why every number in this series exists.
The scoreboard
Here are the signals. I have left out the weights and thresholds on purpose; the categories are the interesting part anyway, and the right-hand column is the honest part.
| What it catches | How it gets fooled | |
|---|---|---|
| User agent claims | Empty user agents, self-declared libraries, browser versions that retired years ago | Copy a real browser's user agent. Takes ten seconds |
| Header consistency | Clients that claim to be a browser but forget what browsers always send | Copy the full header set too. Takes a minute |
| TLS fingerprint (JA4) | Scripting libraries and frameworks wearing a browser name tag | Browser-impersonating TLS libraries, or a real browser |
| HTTP/2 fingerprint | The stacks that faked the TLS hello but not the conversation after it | Faking the full HTTP/2 stack, or a real browser |
| Crawler verification | Impostors calling themselves Googlebot or Bingbot | Not really: you cannot fake Google's DNS |
| Behaviour | Visitors that read page after page without loading a single image | Automated real browsers load assets like anyone else |
| Client checks during the challenge | Automation flags and inconsistencies a real browser does not have | Stealth plugins, which is why this is never decisive |
| Reputation | Addresses the community has already seen misbehaving | Fresh residential addresses have a clean record |
| Request pressure | Visitors hammering the store far faster than anyone shops | Spread the load over thousands of addresses |
| Cold deep links | First visits that land straight on a filtered or parameterised URL | Easily, on its own. Which is why it is one line on the scoreboard, not a rule |
| Firewall hits | Requests that carry attack payloads | Nothing subtle: this one ends the conversation |
Read the right-hand column. Almost everything can be fooled on its own. That is the whole argument for scoring: a bot has to fool all of them, at the same time, while still looking like the same visitor. Each extra column it has to beat costs it money, time or both.
Four ways a request can end
Pass. The page is served, nothing happens. This is where nearly every shopper lives.
Challenge. The real page is served, and a small proof-of-work puzzle solves in the background. The shopper does not notice. A script that cannot run JavaScript never gets its pass.
Ban. A short interstitial page that solves itself, or asks for a click on the harder cases.
Block. A plain refusal. Reserved for the certain cases.
Across multiple production stores over a given period, 82% of requests passed untouched, 3.4% were challenged invisibly, 8.2% hit the interstitial and 1.5% were blocked outright. Looking only at page requests, 19% came from a clean browser, 31% were verified search engines, and the rest was automated or suspicious. Your analytics will never tell you that, because most of those visitors never run your analytics script.
Googlebot, or "Googlebot"
Crawler verification is the one signal that is close to unfakeable, and it produced my favourite number of the whole series.
For anything claiming to be a search crawler, we look up the hostname behind the connecting address, check that it belongs to the search engine, then look that hostname up again and confirm it points back to the same address. It is the method Google itself recommends. The result is cached, so it costs almost nothing.
Over the same period, 210 of the 408 addresses that called themselves Googlebot were fake. Bing, by comparison, had 3 impostors out of 289. Apparently nobody dresses up as Bing. The fakes were refused 97% of the time; the real Google sent 98% of the Googlebot traffic and was never challenged once, because a store that blocks Google has solved the bot problem in the least useful way possible.
The hall of shame
Every signal in that table has, at some point, fired on someone it should not have. Here is the list, because pretending otherwise would be the least credible thing in this post.
Our own dashboard. Banned by our own edge, the same week the scoring went live. Clean work.
Home internet on IPv6. Some residential providers give their customers reverse-DNS names that looked suspicious to the crawler check. Real people, flagged for their ISP's naming taste.
Facebook link previews. Somebody shares a product, Facebook fetches it, we refuse Facebook. Not ideal for a shop.
Google Ads and newsletter clicks. They arrive with long tracking parameters, which looked a lot like a bot guessing URLs. We relaxed that signal. Scrapers noticed and started dressing up as ad clicks. We tightened it again, more carefully.
Our own colleagues. Team members on certain ISP or VPN, where a lot of home traffic looks like data centre traffic, got throttled. We changed how much that signal is allowed to count.
Every one of these was caught because every signal is logged, and fixed by adjusting one weight rather than tearing out a layer. That is the other benefit of scoring: mistakes are tunable, not fatal.
Why not just block by address?
Because addresses have stopped meaning anything. On a day in September, one store saw 32,462 refused requests in one hour from 31,201 different addresses. Roughly one request each. A per-address rule sees thirty-one thousand polite strangers.
Many of those addresses are residential proxies: real home and mobile connections rented out to scrapers. Blocking them outright also blocks the shopper who happens to share that connection tomorrow. So the score has to judge the visit, not the address, and the next part of this series, about proof of work, is how we make those visits expensive instead of trying to blacklist the planet.
Finally, measuring it and constantly update algorithm
An anti-bot layer you cannot see is a rumour. Every decision the edge makes lands in a central log store, off the store itself, with every signal attached.
None of it is perfect, and none of it has to be, I don't think it ever will. The score does not need to be right about every visitor. It needs to be right about enough of them, cheaply, while the other layers catch what it misses. Finding the right balance between acessibility and security.
Numbers in this post come from the edge logs of selected production stores we operate, over a given period — about 8.5 million requests. Store names are left out on purpose.
Next up, Part 5: Self-Hosted Proof of Work with ALTCHA.
The anti-bot series: Part 1: Overview · Part 2: OpenResty vs NGINX, Caddy and Traefik · Part 3: How to Spot a Fake Chrome · Part 4: How to Build a Bot Score · Part 5: Self-Hosted Proof of Work with ALTCHA.
StoreFrame scores every request at an OpenResty edge in front of every Magento store it runs: fingerprints, crawler verification, behaviour and reputation, with every decision logged centrally.
See how StoreFrame protects Magento storesA founder, an engineer at heart, an independent consultant who seek alternatives to the mainstream — Currently focused in burning AI tokens to deliver the best agentic eCommerce experience.
More Articles
More Articles
Helio is the small agent on every server StoreFrame runs. It watches the server, the containers and the store, reports live, keeps your history on your own server, and takes work back. Now in Rust.
Mago is the open-source admin assistant shipping with Mage-OS 4. Who builds it, why it beats the first attempt, the MCP addon I built at the Zwolle hackathon, and what it really costs.
So you know the person behind it. Not a sales pitch, just what StoreFrame is to me: a home for my team, my notes as working code, and the impossible thing I'm glad I tried to build.
A PHP vulnerability dropped the night before Meet Magento Germany. Ten things I took home: about people, patching, merchants who choose offline, and why badges don't stop bugs.
PWA Studio, Vue Storefront, GraphCommerce, Rapidez, Breeze and Hyva: why headless Magento kept losing to cost, and why AI that writes JavaScript fluently may finally flip the verdict.
Every Magento merchant asks whether the platform will still be here, and still be free, in five years. We stopped answering shop by shop and moved every customer to Mage-OS. Here's why.